
Observability rebuild for a foodtech platform
Cut mean-time-to-detect 72% for a food-delivery platform with unified tracing and SLOs.
72%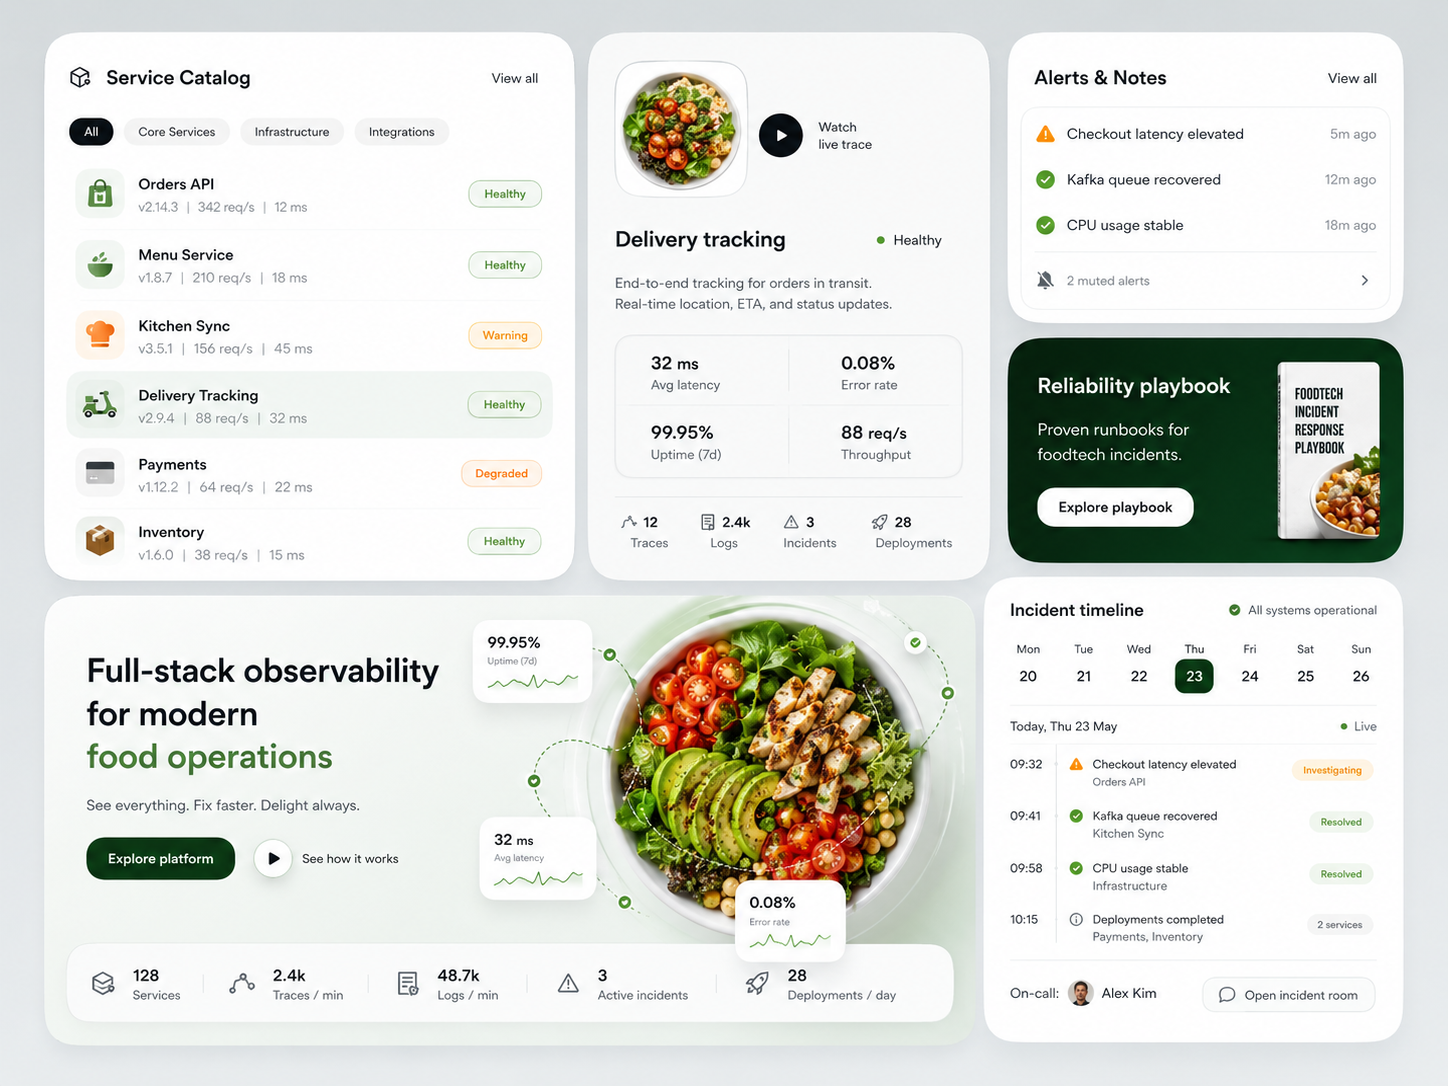
Problem, approach, and the outcome
The client is a UK food-delivery platform whose revenue concentrates sharply into dinner-rush peaks. During those windows, every minute of a partial outage translates directly into failed orders and lost revenue.
Their observability was fragmented across disconnected tools, so diagnosing incidents at peak was slow and stressful.
At dinner-rush peaks, exactly when revenue concentrates, incidents turned into a scavenger hunt across disconnected tools while orders quietly failed. The tooling worked against the team at the worst possible moment.
Engineers correlated signals by hand across systems that did not talk to each other, so detection lagged customer impact badly. Problems were felt by customers before they were seen by engineers.
The platform needed to see problems as customers felt them, in real time. Detection had to be tied to customer impact, not to noisy infrastructure signals.
We instrumented services with OpenTelemetry, producing consistent traces, metrics, and logs from one standard. A single, consistent signal set is what makes fast diagnosis possible.
Those signals were unified behind a single pane, so engineers stop hunting and start diagnosing. The scavenger hunt was replaced by a coherent picture.
We set SLOs that page on genuine customer impact (like failed orders) rather than on noisy infrastructure metrics, and tuned alerting against real incidents so pages meant something and fatigue dropped. Alerts now signal problems customers actually feel.
- 72% cut in mean-time-to-detect
- One pane across logs, metrics, and traces
- SLO alerting on failed-order impact
- Alert noise cut so pages signal real customer impact
More Cloud & DevOps case studies
GxP-compliant CI/CD for a pharma manufacturer
Delivered validated, GxP-compliant CI/CD, cutting release lead time 8x with full audit evidence.
Read the full case study
CI/CD overhaul for a fintech
Lifted release frequency 15x with automated gates and one-click rollback.
Read the full case study
Datacenter exit for an NHS hospital group
Migrated 900 clinical workloads off two datacentres to the cloud with zero downtime on patient-facing systems.
Read the full case studyGet a senior architect on the call, first time, every time.
No SDR gauntlet. 30 minutes with an engineer who can scope the problem, name the risks, and give you an honest feasibility call.