Skip to content
BritonOne Technology
Cloud & DevOpsDevOps Engineering

Ship weekly with rollback under five minutes

CI/CD, IaC, GitOps, and SRE practice for FCA, PRA, EBA, and HIPAA-supervised firms: release rhythm your engineers actually want with the change-evidence trail your auditors actually need.

0xMedian deploy-frequency uplift year one
0 minMean-time-to-recovery on the new pipeline
0%Auditable change records, no manual rework
DevOps engineer monitoring CI/CD pipeline dashboards across multiple displays
DevOps disciplines

Every layer of the regulator-fluent pipeline

From the merge gate your engineers see to the SRE practice your supervisor reviews. Each sub-discipline is staffed by senior engineers who have shipped the same pattern across regulated estates.

CI/CD Pipelines

Core service

GitHub Actions, GitLab CI, CircleCI, or Argo Workflows: pipelines that build, test, scan, sign, and deploy with change evidence at every gate.

  • Build and test
  • Sign and deploy
  • Gated change evidence
Infrastructure as Code

Platform

Terraform, Pulumi, AWS CDK, Bicep: modular, tagged, policy-checked at plan time with OPA / Sentinel and managed state with drift detection.

  • Modular tagged modules
  • Plan-time policy checks
  • Managed state, drift detection

GitOps

Automation

Argo CD or Flux for declarative cluster state: every change is a pull request, every rollback is a revert, audit trail is the git log.

  • Declarative cluster state
  • Pull-request changes
  • Revert-based rollback

Supply-chain Security

Security

SBOM generation, Cosign / Sigstore image signing, SLSA L3 provenance, dependency vulnerability scanning blocking at the PR gate.

  • SBOM generation
  • Image signing
  • Provenance attestation

Observability Platform

Observability

OpenTelemetry instrumentation, structured logging, RED + USE metrics, distributed tracing, audit-grade retention into your existing SIEM.

  • OpenTelemetry instrumentation
  • Distributed tracing
  • Audit-grade retention

SRE Practice

Reliability

SLO definition, error budgets, on-call rotation, runbooks, postmortem culture: the SRE practice exists in writing, not just in heads.

  • SLOs and error budgets
  • On-call rotation
  • Runbooks and postmortems
Regulated estates onlyFCA · PCI · HIPAA · SOC 2 programs
Senior-led deliveryArchitects & engineers with real-world delivery
Proven patternsReusable blueprints, automations, and guardrails
Outcome focusedLower risk, faster delivery, measurable impact
What changes when the pipeline does the evidence work

Convert quarterly mega-releases into a weekly rhythm

Where 2018-era CAB processes paper over the lack of automated evidence, a regulator-fluent pipeline earns the release cadence back. Every left-hand pain becomes a right-hand outcome on the first weekly cutover.

BEFORE
  • Quarterly Mega-Releases
  • Manual CAB Approval Bottlenecks
  • Post-Hoc Change Evidence
  • Unsigned Container Images
  • Tribal On-Call Runbooks
  • Inconsistent Observability
  • Hours-Long Mean-Time-to-Recovery
AFTER

Your DevOps Practice Live

100% Evidenced
  • Weekly release cadence

    Small, frequent, well-evidenced changes ship every week. Auditors prefer them and engineers actually want to write them.

    Solved
  • Retrospective CAB on dashboard

    Pipelines auto-generate change records (artefact lineage, test evidence, scan results, approver, rollback plan). CAB reviews a dashboard, not a slide deck.

    Solved
  • SLSA L3 provenance by default

    Every artefact signed at build with Cosign; provenance attestation against source commit, build environment, and dependency lockfile.

    Solved
  • Every change is a pull request

    Argo CD or Flux make cluster state declarative. Rollbacks are reverts, and the audit trail is the git log nobody can rewrite.

    Solved
  • Distributed tracing at every hop

    OpenTelemetry traces, RED + USE metrics, structured logs render the same shape across every service. Incident triage stops being archaeology.

    Solved
  • SLO + error-budget discipline

    SLOs defined per service, error budgets reviewed weekly, on-call rotation runs against runbooks. Postmortems become a culture, not a one-off.

    Solved
  • Eight-minute MTTR

    Observability uplift + rollback automation collapse mean-time-to-recovery from hours to minutes, measured, not asserted.

    Solved
Hyperscalers we run the pipeline on

Three clouds, one release rhythm

Cloud-provider-agnostic pipelines with first-class integration into each hyperscaler's native gates, identity, and audit surfaces.

Amazon Web Services

Default for EKS + Lambda release pipelines

Advanced Partner
  • Argo CD on EKS with IRSA-scoped deploy roles
  • CodeBuild + CodePipeline where regulator demands AWS-native
  • ECR image scanning + Cosign signatures verified at deploy
  • CloudTrail wired into supply-chain evidence trail
EKSArgo CDIRSACodePipelineECRCloudTrail

Microsoft Azure

Default where Azure DevOps anchors source control

Solutions Partner
  • Azure DevOps Pipelines + Azure Container Registry
  • AKS with GitOps via Flux + Workload Identity
  • Bicep + Deployment Stacks for IaC
  • Defender + Sentinel evidence in the change record
Azure DevOpsAKSFluxBicepACRDefender

Google Cloud

Default for data + ML-heavy delivery

Partner
  • Cloud Build + Cloud Deploy with binary authorization
  • GKE Autopilot with Config Sync + Policy Controller
  • Artifact Registry with vulnerability scanning
  • Security Command Center findings in the change record
Cloud BuildCloud DeployGKE AutopilotConfig SyncArtifact RegistrySCC
Design constraints we never trade

Four pillars hard-wired into every pipeline

These are load-bearing for any DevOps practice we run, not stage gates, not afterthoughts. Each pillar lives in the pipeline from week one.

01

Change-Evidence Automation

Every deploy auto-generates artefact lineage, test evidence, scan results, approver, and rollback plan. CAB reviews retrospective dashboard.

  • Pipeline emits change record per deploy
  • Evidence rendered against the source commit
  • Retrospective CAB dashboard for supervisors
  • Zero manual change-record reconstruction
02

Supply-chain Security

SLSA L3 provenance by default: Cosign signatures, SBOM generation, dependency vulnerability gating, blocked at the PR not the deploy.

  • Cosign image signing at build
  • SLSA L3 provenance attestation
  • Trivy / Snyk gates at PR and at deploy
  • Daily dependency scans not just PR scans
03

Observability Backbone

OpenTelemetry-first instrumentation, RED + USE metrics, structured logs, distributed traces, audit-grade retention into your existing SIEM.

  • OpenTelemetry collectors per cluster
  • RED + USE metrics per service
  • Distributed tracing wired into runbooks
  • Audit-grade log retention windows
04

SRE Practice

SLOs, error budgets, on-call rotation, runbooks, and postmortem culture: the SRE practice exists in writing, not just in heads.

  • SLO + error-budget framework per service
  • On-call rotation with runbooks reviewed quarterly
  • Blameless postmortem cadence
  • Severe-but-plausible scenario rehearsals
Our engagement workflow

Seven stages from first call to ongoing support

Every engagement walks the same path, sized to your problem, but with the same verification gates baked in.

  • Phase 01

    Discovery

    Two-week paid sprint. Architect-led. Output: regulator map, costed roadmap, signed scope.

  • Phase 02

    Planning

    Pod composition, sequenced milestones, change-control governance, and risk register.

  • Phase 03

    Design

    Reference architecture, threat model, design system, and acceptance criteria locked.

  • Phase 04

    Development

    Weekly demos, trunk-based, CI/CD from day one. Code reviewed against spec at every gate.

  • Phase 05

    Testing

    Unit, integration, e2e, security, performance, and accessibility, automated and gated.

  • Phase 06

    Deployment

    Blue-green or canary, observability live before launch, rollback rehearsed.

  • Phase 07

    Support

    Managed services or hypercare hand-off. Defined SLOs, named on-call, monthly reviews.

Success stories

Programmes we have shipped

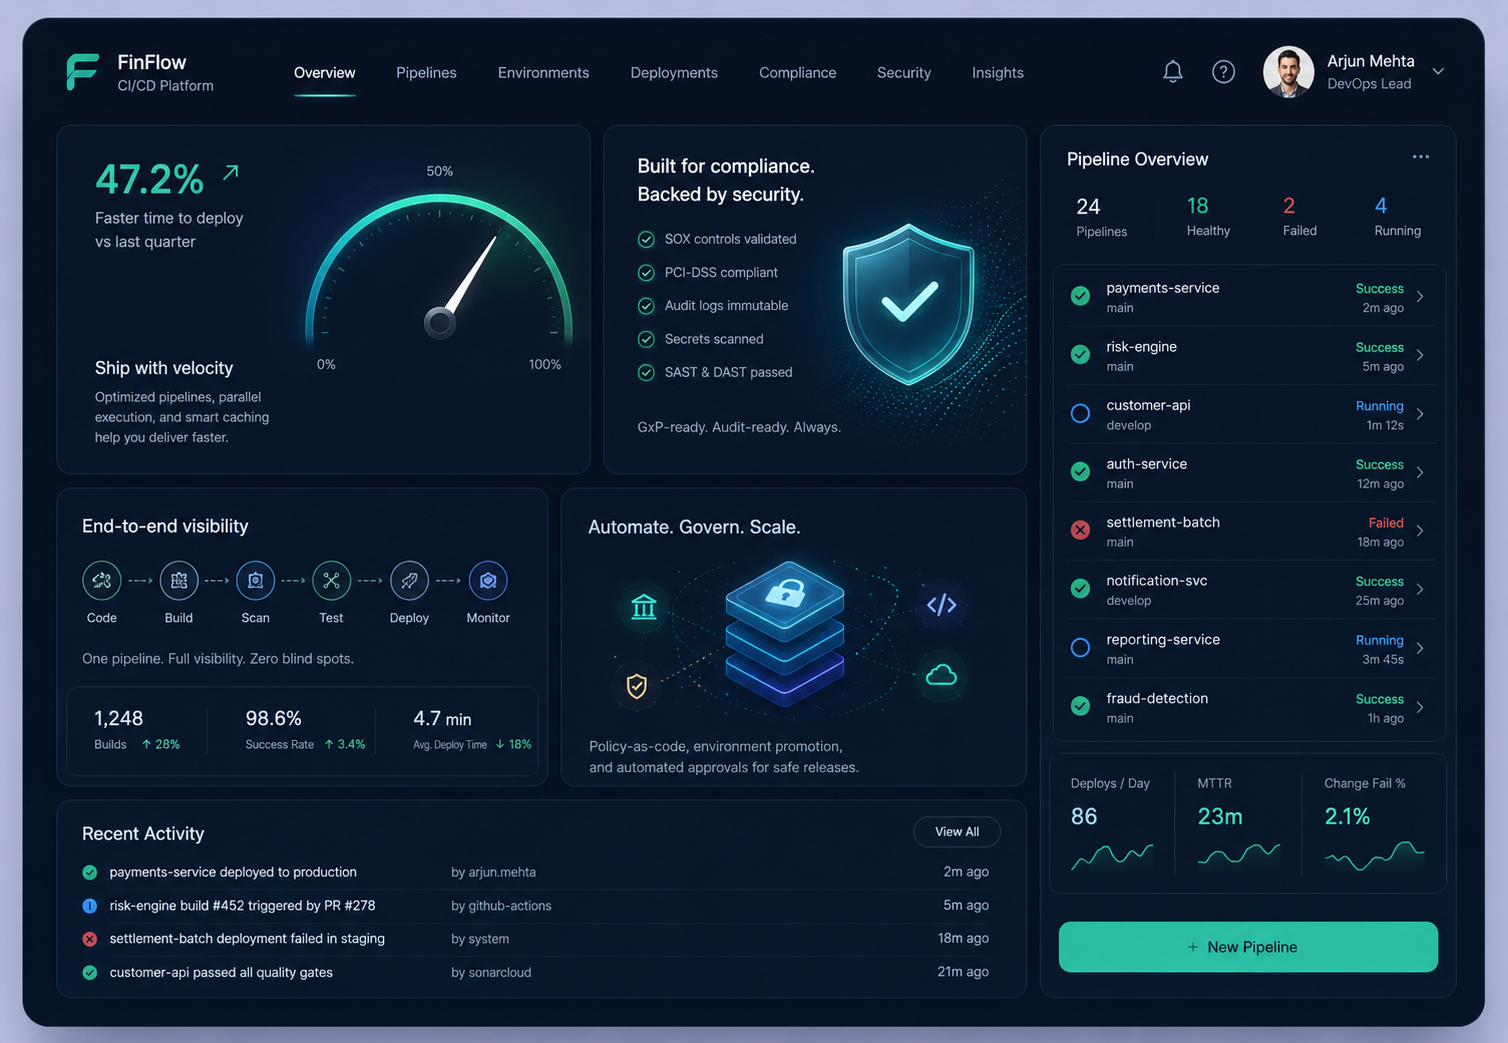
GxP-compliant CI/CD for a pharma manufacturer
8x
Pharma

GxP-compliant CI/CD for a pharma manufacturer

Delivered validated, GxP-compliant CI/CD, cutting release lead time 8x with full audit evidence.

GitLab CITerraformKubernetesAnsible
Country · CH
CI/CD overhaul for a fintech
15x
Fintech

CI/CD overhaul for a fintech

Lifted release frequency 15x with automated gates and one-click rollback.

GitHub ActionsArgo RolloutsKubernetesTerraform
Country · UK
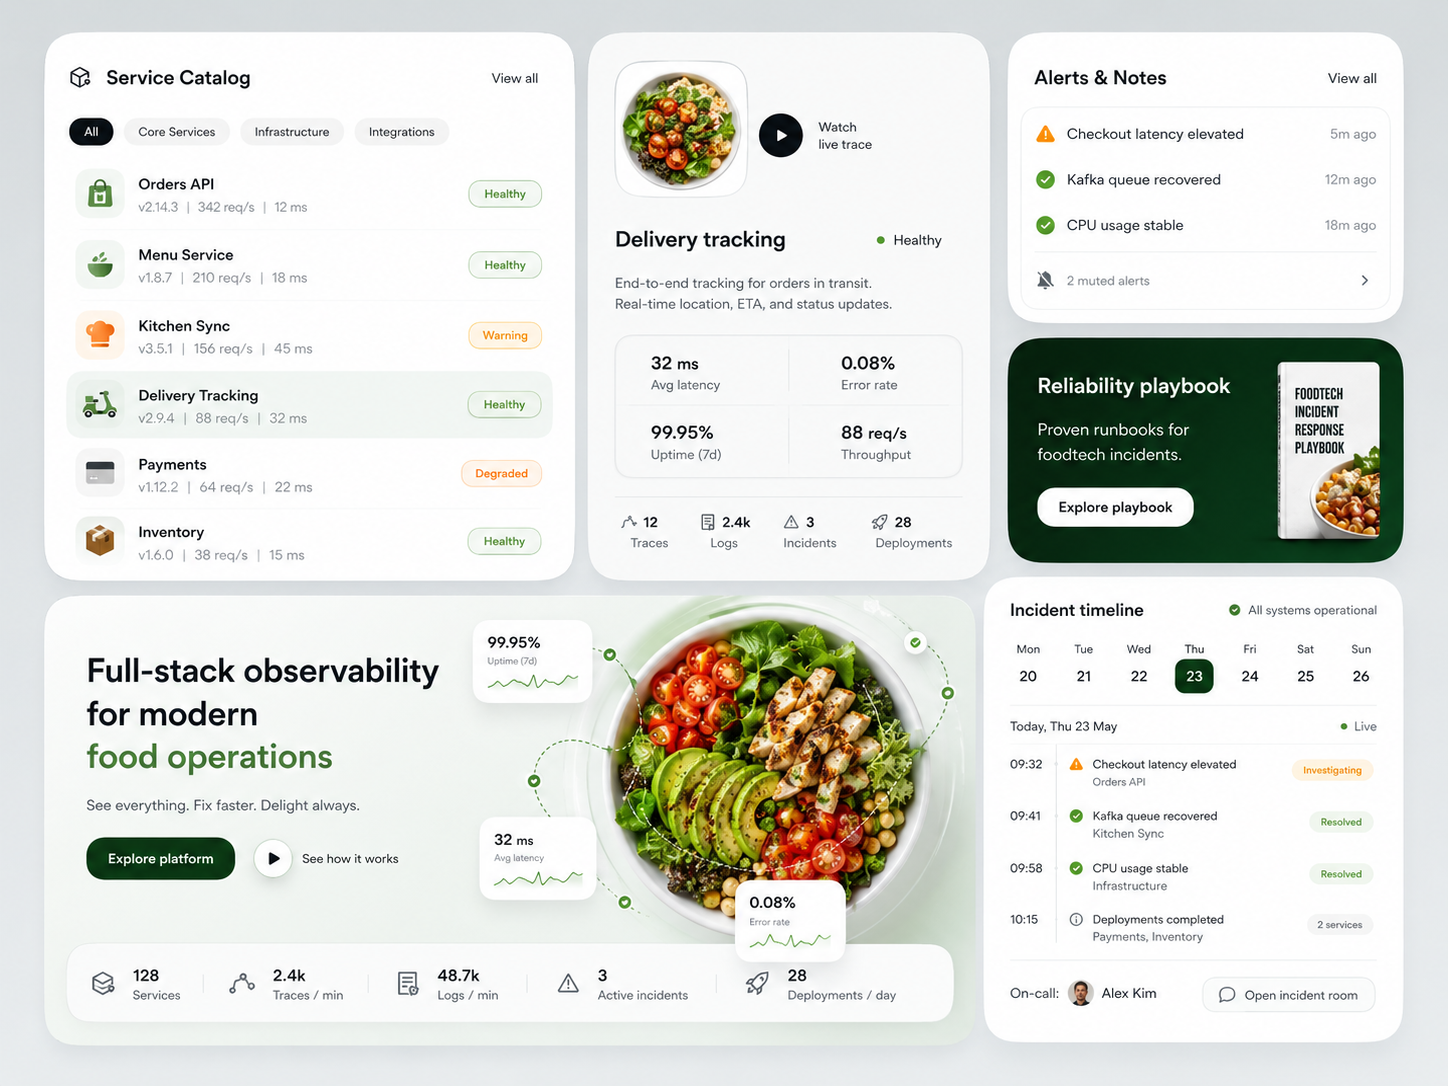
Observability rebuild for a foodtech platform
72%
Foodtech

Observability rebuild for a foodtech platform

Cut mean-time-to-detect 72% for a food-delivery platform with unified tracing and SLOs.

OpenTelemetryGrafanaPrometheusTempo
Country · UK
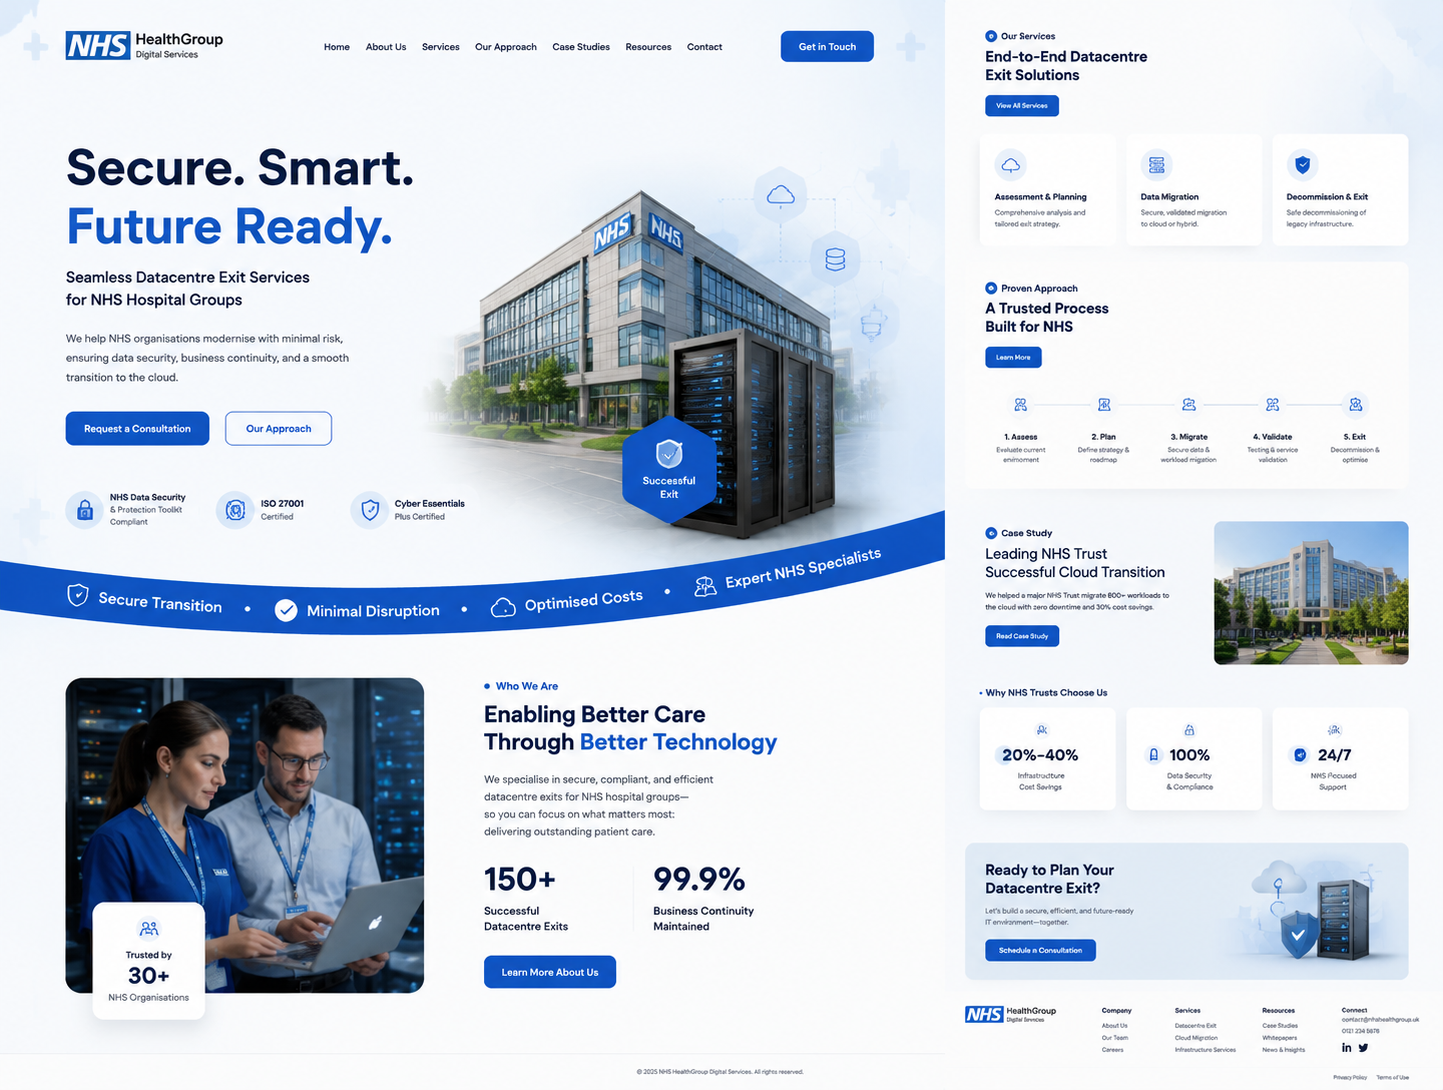
Datacenter exit for an NHS hospital group
900
Healthcare

Datacenter exit for an NHS hospital group

Migrated 900 clinical workloads off two datacentres to the cloud with zero downtime on patient-facing systems.

AzureTerraformAzure MigrateAnsible
Country · UK
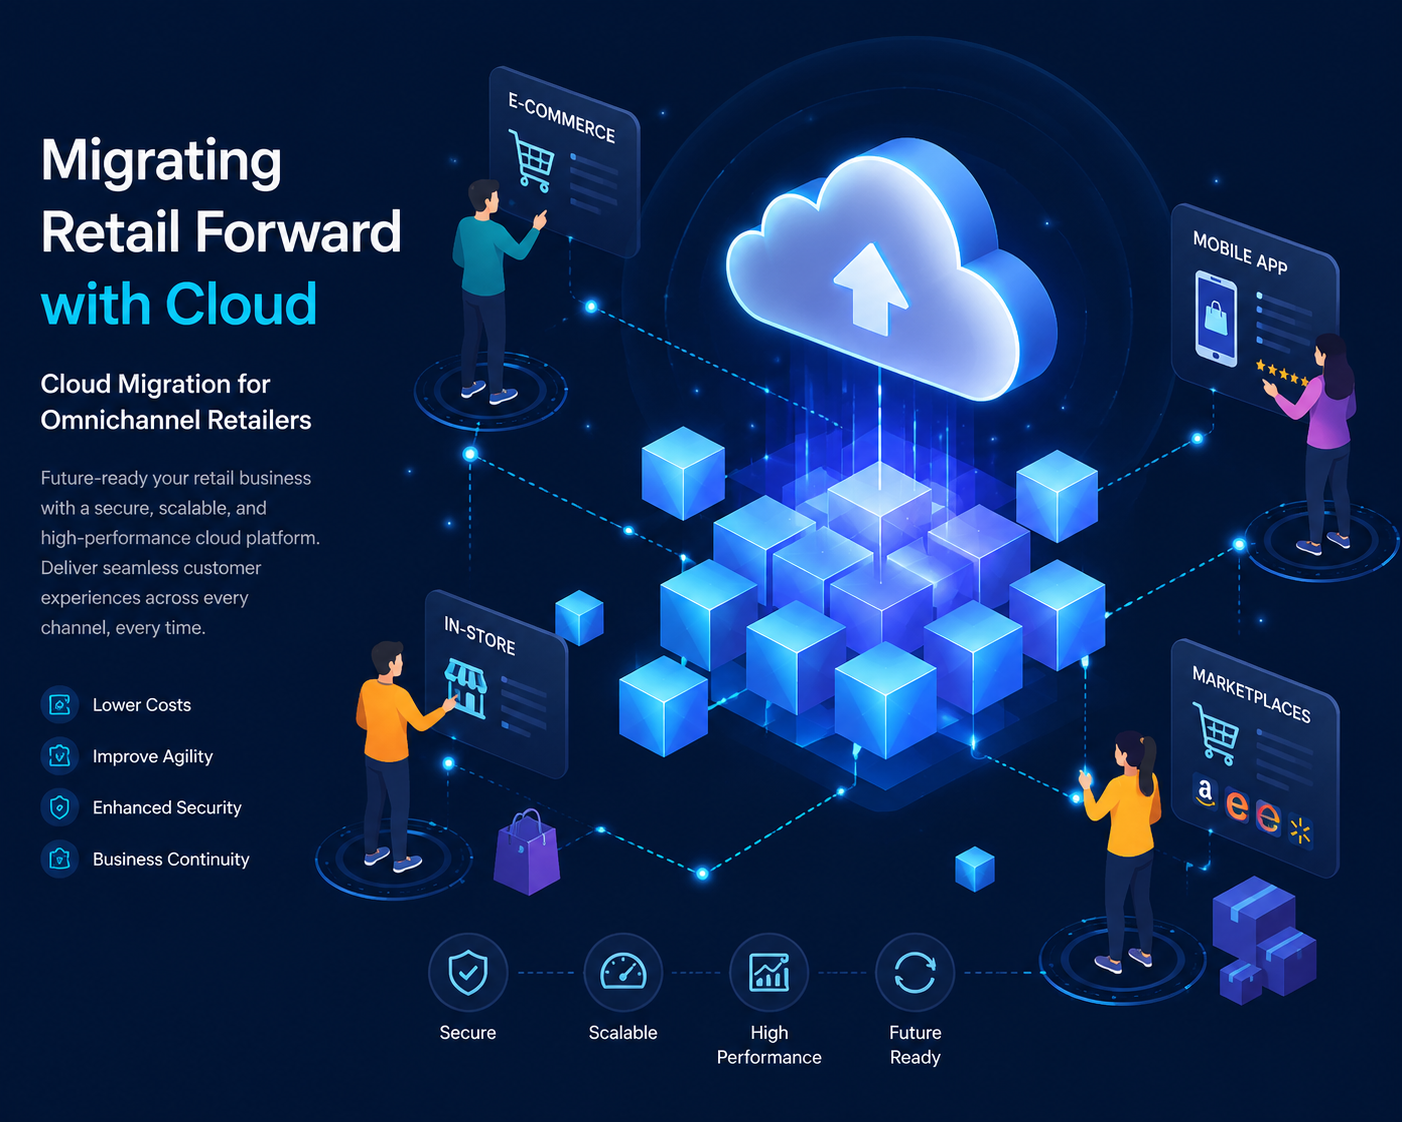
Cloud migration for an omnichannel retailer
0 outages
Retail

Cloud migration for an omnichannel retailer

Re-platformed e-commerce to the cloud, holding availability through a record peak-season trading day.

AWSTerraformEKSCloudFront
Country · UK
Factory-systems migration for a manufacturer
34%
Manufacturing

Factory-systems migration for a manufacturer

Lifted MES and quality systems to the cloud across nine plants, cutting infrastructure cost 34%.

AzureTerraformAKSAzure Arc
Country · DE
Connected-vehicle platform for a carmaker
1.2M
Automotive

Connected-vehicle platform for a carmaker

Built a cloud platform ingesting telemetry from 1.2M connected vehicles at scale.

GCPKubernetesPub/SubBigQuery
Country · DE
Secure landing zone for a government department
7 weeks
Government & Public

Secure landing zone for a government department

Stood up a compliant, multi-account landing zone for a government department in 7 weeks.

AWSControl TowerTerraformSCPs
Country · UK
Kubernetes platform for a logistics operator
55%
Logistics

Kubernetes platform for a logistics operator

Consolidated 14 clusters to one governed platform, cutting ops toil 55% for a logistics operator.

KubernetesIstioFluxTerraform
Country · NL
24/7 SRE for a telemedicine platform
99.98%
Telemedicine

24/7 SRE for a telemedicine platform

Ran a telemedicine platform to a 99.98% SLO with a follow-the-sun on-call.

KubernetesPrometheusPagerDutyTerraform
Country · UK
Managed FinOps for a biotech scale-up
37%
Biotech

Managed FinOps for a biotech scale-up

Cut monthly cloud spend 37% for a genomics biotech without slowing a single pipeline.

AWSKubecostTerraformAWS Batch
Country · UK
Managed patching and compliance for an insurer
48h
Insurance

Managed patching and compliance for an insurer

Held critical-patch SLA to 48 hours across an insurer's estate, evidenced every cycle.

AnsibleAWS SSMTerraformWiz
Country · UK

Who we are

About us

BritonOne Technology is a full-cycle engineering company that builds and operates production software for regulated estates. Since 2017, we have shipped programmes that clear audit on the first pass across banking, insurance, wealth, healthcare, and biotech. Our teams pair deep domain knowledge with disciplined engineering, treating compliance, security, and resilience as first-class deliverables. From architecture through to live operations, we stay accountable for the systems we build, measuring success by uptime, audit outcomes, and defensible business results.

60+Senior engineers across UK and EU

Why choose us

Engineer experience, average9+ yrs
Specialist replacement window48h
Code and IP ownership, day one100%
Surprise invoicesZero
Why teams choose BritonOne Technology

Four reasons enterprise buyers come back

We don't compete on lowest day-rate. We compete on shipped outcomes inside environments that have to clear audit.

Senior-only delivery

Every engineer on every engagement is at least senior, typically eight to fifteen years deep in their craft. No bench rotations, no junior pyramid hidden behind a glossy proposal, no bait-and-switch after contract signature. The architect who scoped your engagement is the same person committing code by week three.

Audit-ready by default

FCA, PRA, EBA, BaFin, FINMA, HIPAA, SOC 2 Type II: every framework we work under is treated as a design constraint from day one, not a final-stage gate. Evidence trails, model-risk packs, change-control artefacts, and pen-test reports ship alongside the code, ready for second-line review without a remediation sprint.

Anti-drift delivery discipline

Small pods of three to seven engineers, each with a named delivery lead who owns scope, schedule, and outcomes from kickoff to hand-off, never a faceless team you have to chase for an answer. Weekly demos run against the signed scope, frequent verification gates catch regressions early, and quarterly outcome reviews measure real progress against the original business case rather than a moving target. Together those rituals catch scope drift before it has any chance to compound, so programmes that should take six months don't quietly stretch into eighteen, budgets stay anchored to what was agreed, and every milestone ships with a written, testable definition of done that both sides sign off before we move on.

Long-tail support beyond hand-off

We don't disappear the moment the engagement closes. Managed services, hypercare windows, named on-call rotations, or quarterly health checks: pick the depth that matches your operational risk profile. About seventy percent of clients return for a second programme, usually because the team that shipped the first one is still on the other end of the page.

Client Satisfaction Reviews

Words from the teams we have shipped with.

Anonymous under MNDA. Each quote is from a senior buyer who owned the engagement end to end across the services catalogue.

One Team Replacing Two Vendors

BritonOne Technology replaced two of our incumbent vendors with one team. Faster sprints, fewer status meetings, more code shipped per week.

VP EngineeringTier-1 European retail bank
Common pre-engagement questions

Things buyers ask before picking the first service

Frequently asked questions

Yes, and most engagements do. A typical programme bundles two or three services (for example, cloud migration + cloud security + managed ops, or AI consulting + generative AI + data analytics). One statement of work, one delivery lead, one invoice, one accountable line.