
Grounded knowledge copilot for a retail bank contact centre
Cut average handle time 44% across 2,600 agents, with answers grounded in approved policy only.
44%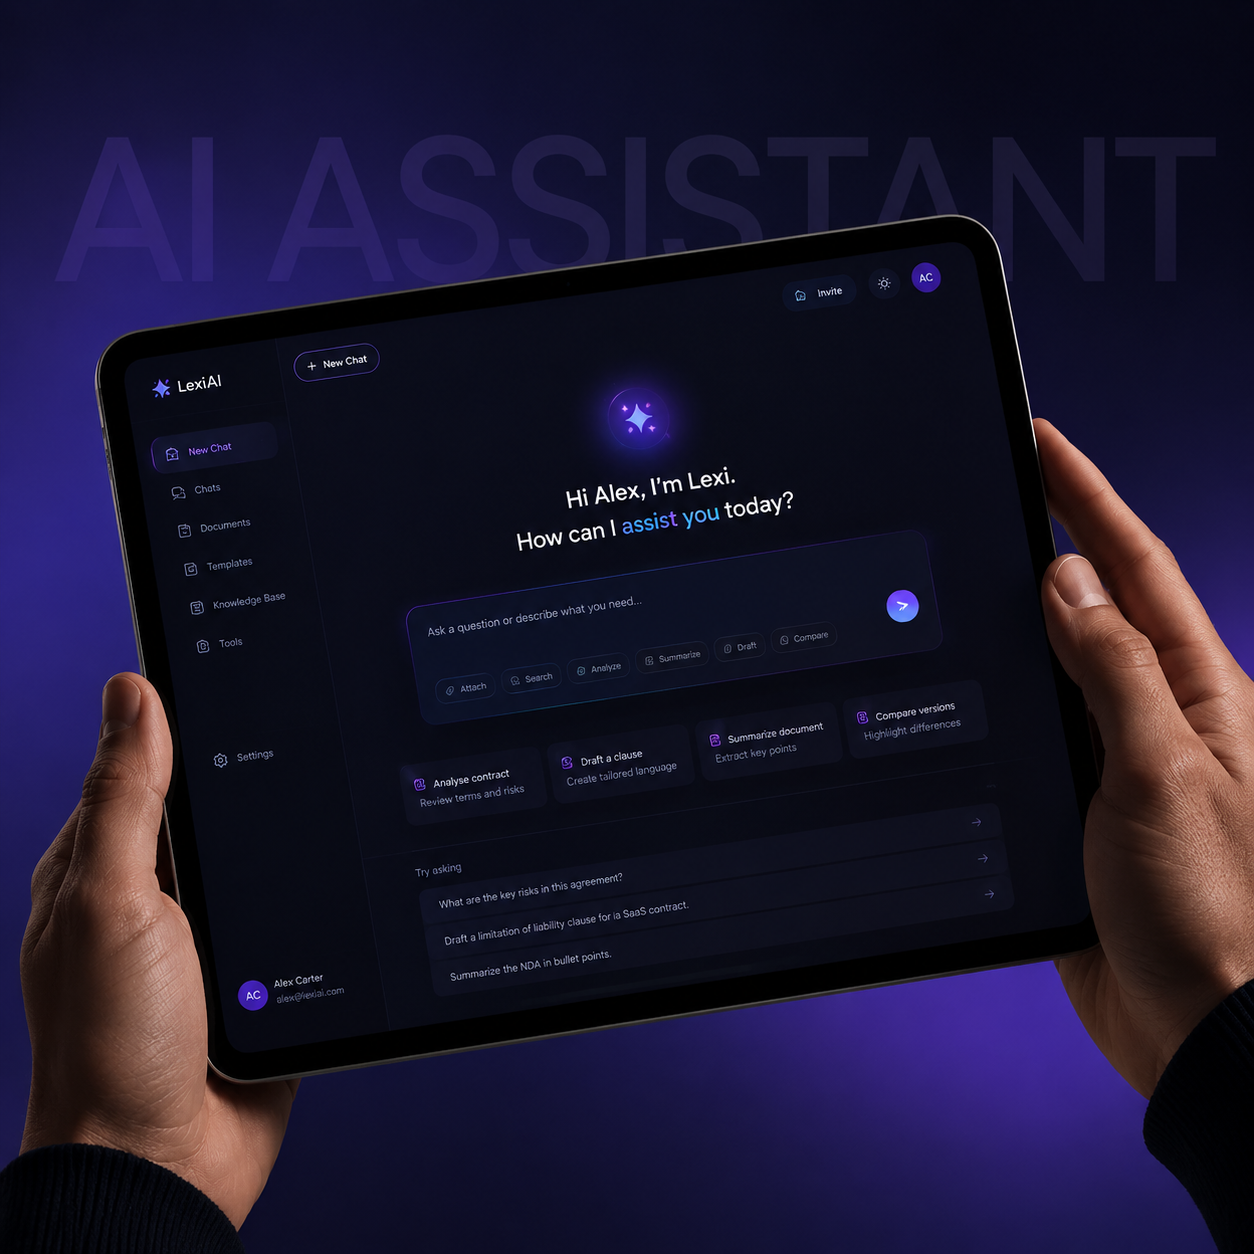
Problem, approach, and the outcome
The client is a UK retail bank running a large contact centre of roughly 2,600 agents handling everything from routine servicing to sensitive complaints. Every interaction is subject to conduct rules, so consistency and accuracy are not nice-to-haves but regulatory obligations.
High agent turnover and a sprawling, fragmented policy estate made it hard to keep answers consistent, and the cost of getting them wrong (in complaints, remediation, and conduct risk) was significant.
Agents hunted across a dozen disconnected policy systems mid-call, keeping customers on hold while they pieced together an answer. The experience was slow for the customer and stressful for the agent, and it produced inconsistent outcomes that carried real conduct risk.
New joiners took months to get fluent in where information lived and how to apply it, so the fragmented estate was also a training and retention problem. Every departure reset the clock on hard-won knowledge.
Compliance would not accept a bot that could improvise beyond approved guidance, which ruled out an off-the-shelf assistant. Anything the bank deployed had to be provably grounded in policy and unable to make things up.
We built a retrieval copilot over the approved policy corpus that refuses to answer when it cannot ground a response in source, rather than guessing. That refusal behaviour was the feature compliance cared about most: silence beats a confident wrong answer on a regulated call.
Every answer cites the policy reference it came from and hands the agent a ready-to-read response they can confirm before speaking, so the human stays accountable for what the customer hears. We tuned retrieval against real call transcripts and wired in a feedback loop, so gaps in the corpus surfaced and got fixed quickly.
Access rolled out team by team with handle-time and quality monitored throughout, so we could prove the tool improved outcomes before scaling it across all 2,600 agents.
- 44% cut in average handle time
- Answers grounded in approved policy, refusing off-source questions
- First-contact resolution up 9 points
- New-agent time-to-competency roughly halved
More AI & Machine Learning case studies
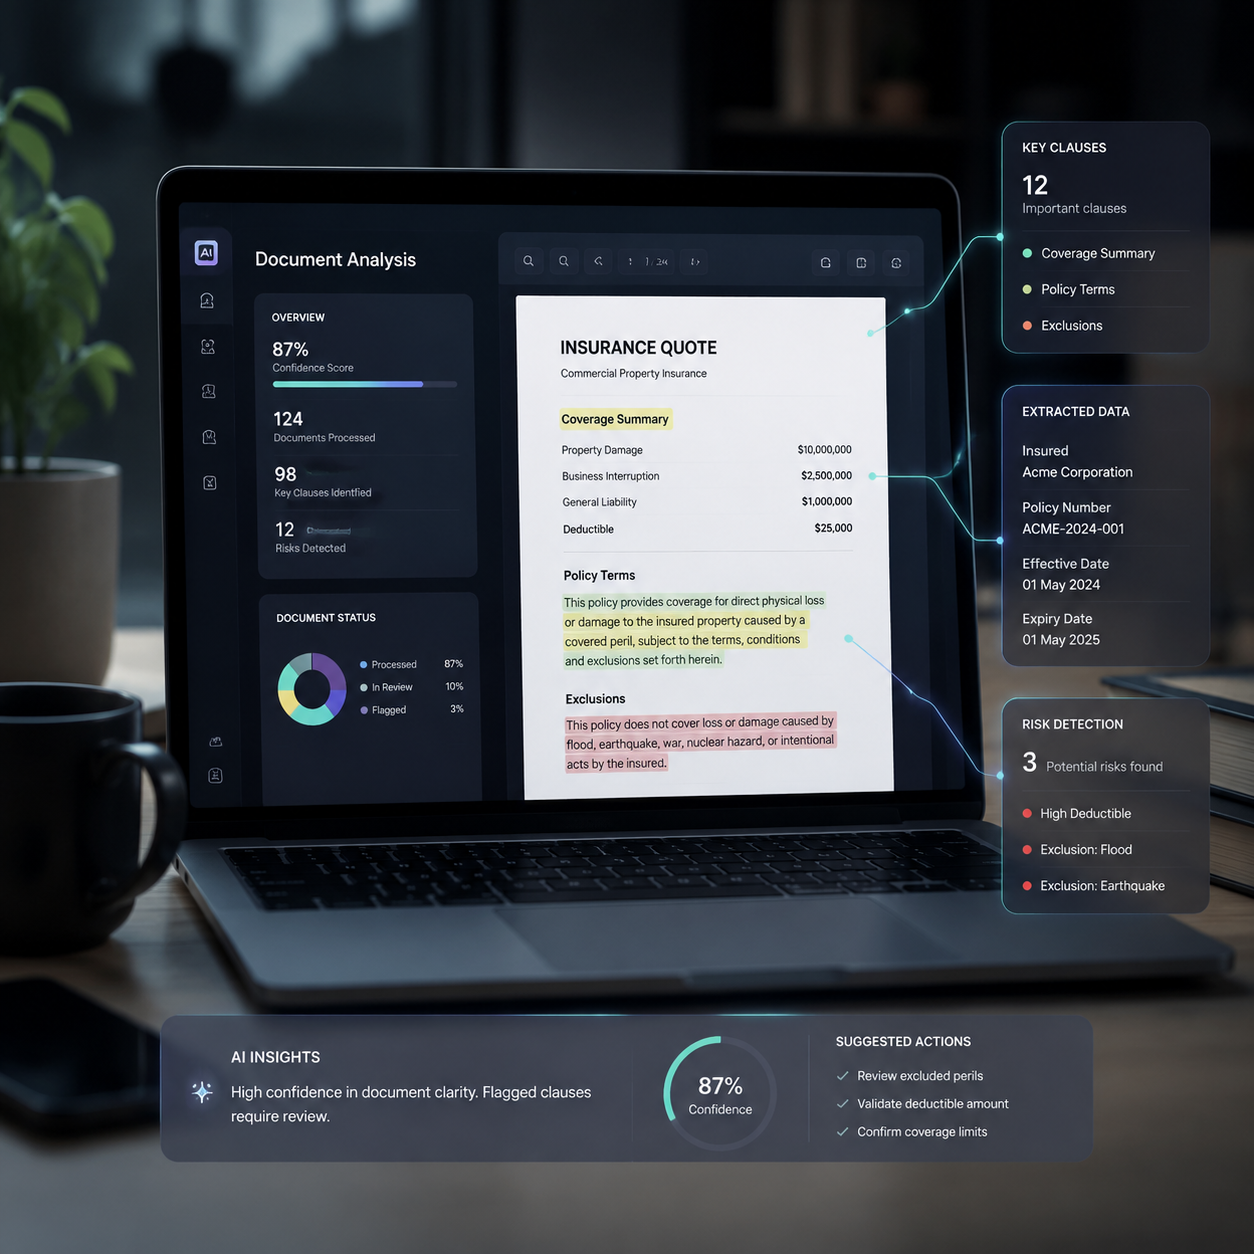
Underwriting copilot for a speciality insurer
Drafted first-pass quotes from submission packs 3.1x faster, every clause cited back to the wording it came from.
Read the full case study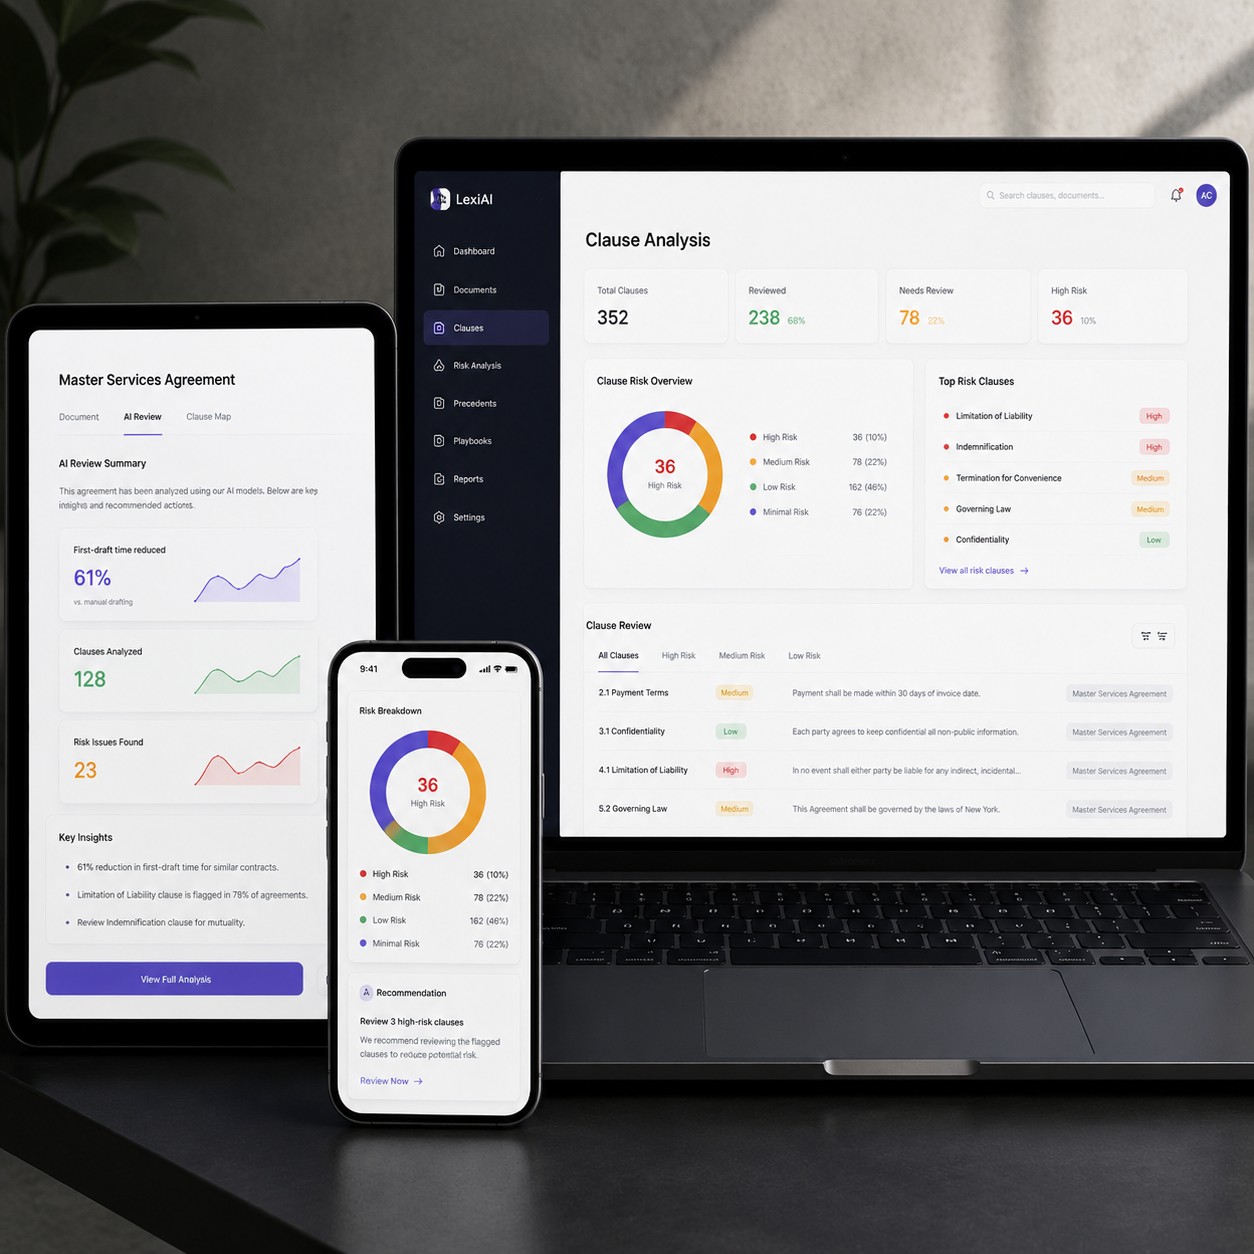
Clause-level contract drafting for a commercial law firm
Cut first-draft time on regulated commercial contracts by 61%, each clause traceable to firm precedent.
Read the full case study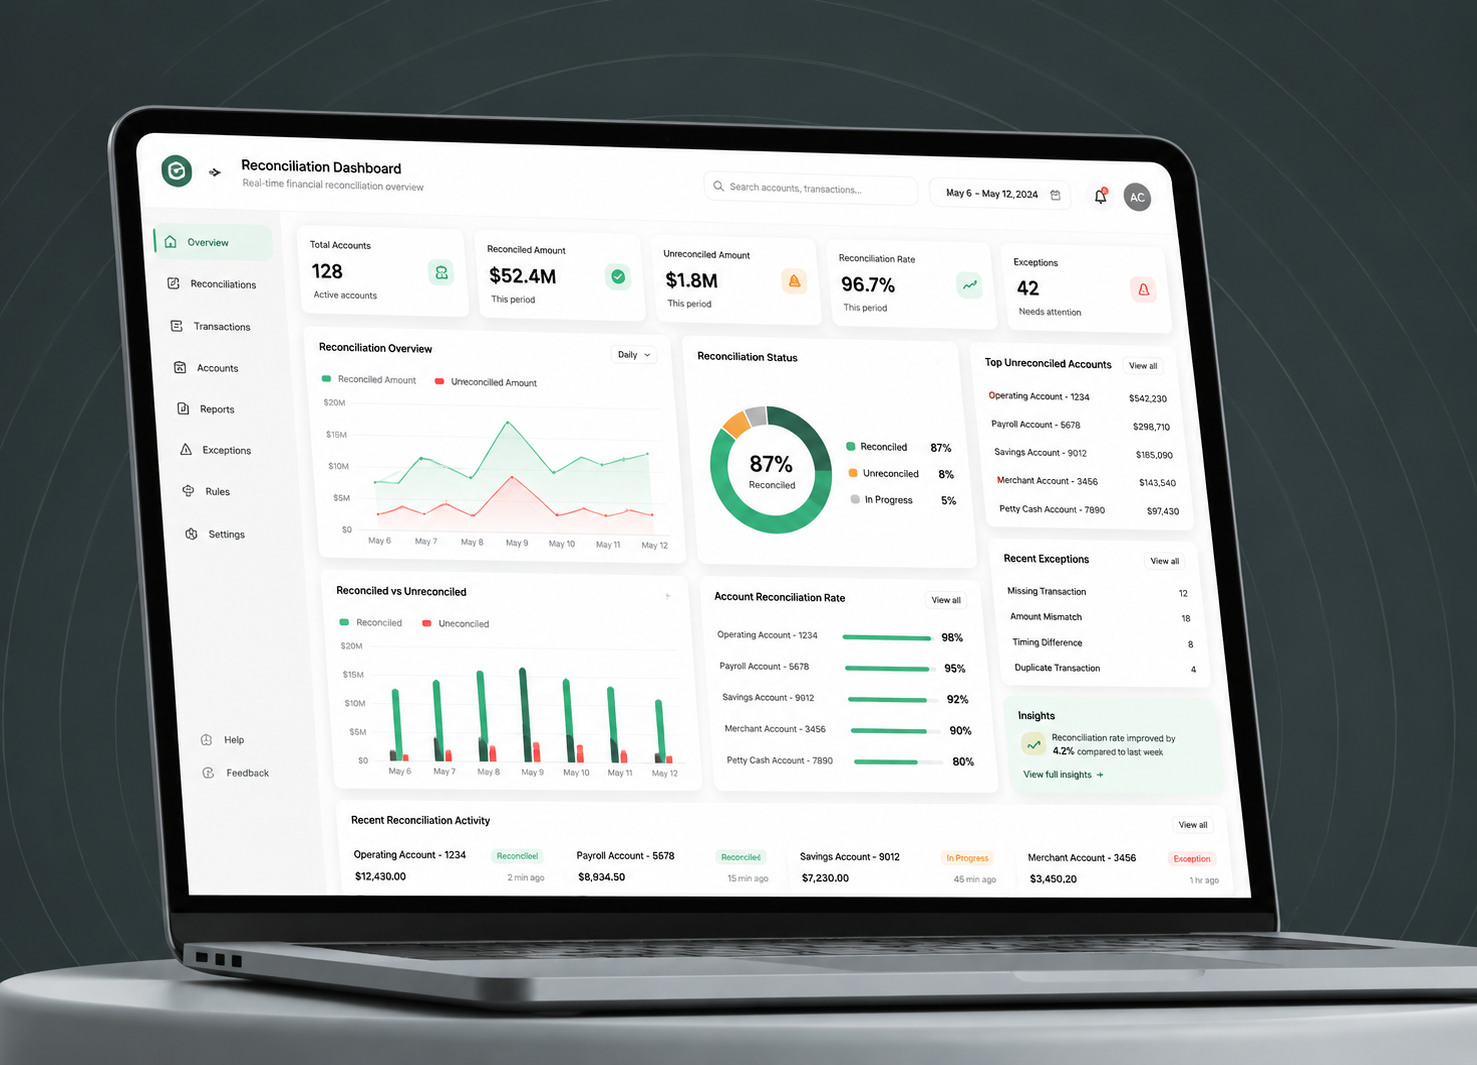
Autonomous reconciliation for a payments processor
Resolved 89% of reconciliation breaks without a human, every action logged for audit.
Read the full case studyGet a senior architect on the call, first time, every time.
No SDR gauntlet. 30 minutes with an engineer who can scope the problem, name the risks, and give you an honest feasibility call.